AI Agent Memory Is Not Just Chat History
Your agent does not remember anything. It re-reads a transcript that keeps getting trimmed. Here are the four memory layers that actually fix it, with code.

Most agents that claim to have memory do not have memory. They have a Python list of messages, and every turn they resend the whole thing to the model. That is not recall. That is re-reading. AI agent memory only starts once you decide what happens to a fact after the transcript is gone.
This works fine for the first twenty turns. Then a real session runs long, the list gets trimmed to fit the window, and the order number the customer gave you on turn three quietly disappears. The agent does not throw an error. It just asks the question again and looks slightly stupid.
I have watched teams respond to this by upgrading to a model with a larger context window. It buys a few weeks. The failure comes back at a bigger scale, and now it costs more per turn.
Why The Message Array Breaks
The message array is doing four unrelated jobs at once, and it is bad at three of them.
It is holding the current task's scratch state. It is holding the recent dialogue. It is holding facts about the user that should outlive this conversation entirely. And it is holding stale copies of data that lives in your database, which may have changed thirty seconds ago.
Those four things have completely different lifespans. When you store them in one structure, you can only apply one eviction rule to all of them, and any eviction rule you pick will be wrong for at least three of the four.
Trim the oldest messages and you lose the durable user facts, because those were stated early. Summarise aggressively and you lose the precise tool output the current step depends on. Keep everything and you pay for a 90k token prompt to answer a two sentence question.
There is no correct trimming strategy for a structure that mixes lifespans. The structure is the problem.
The Four Layers Of AI Agent Memory
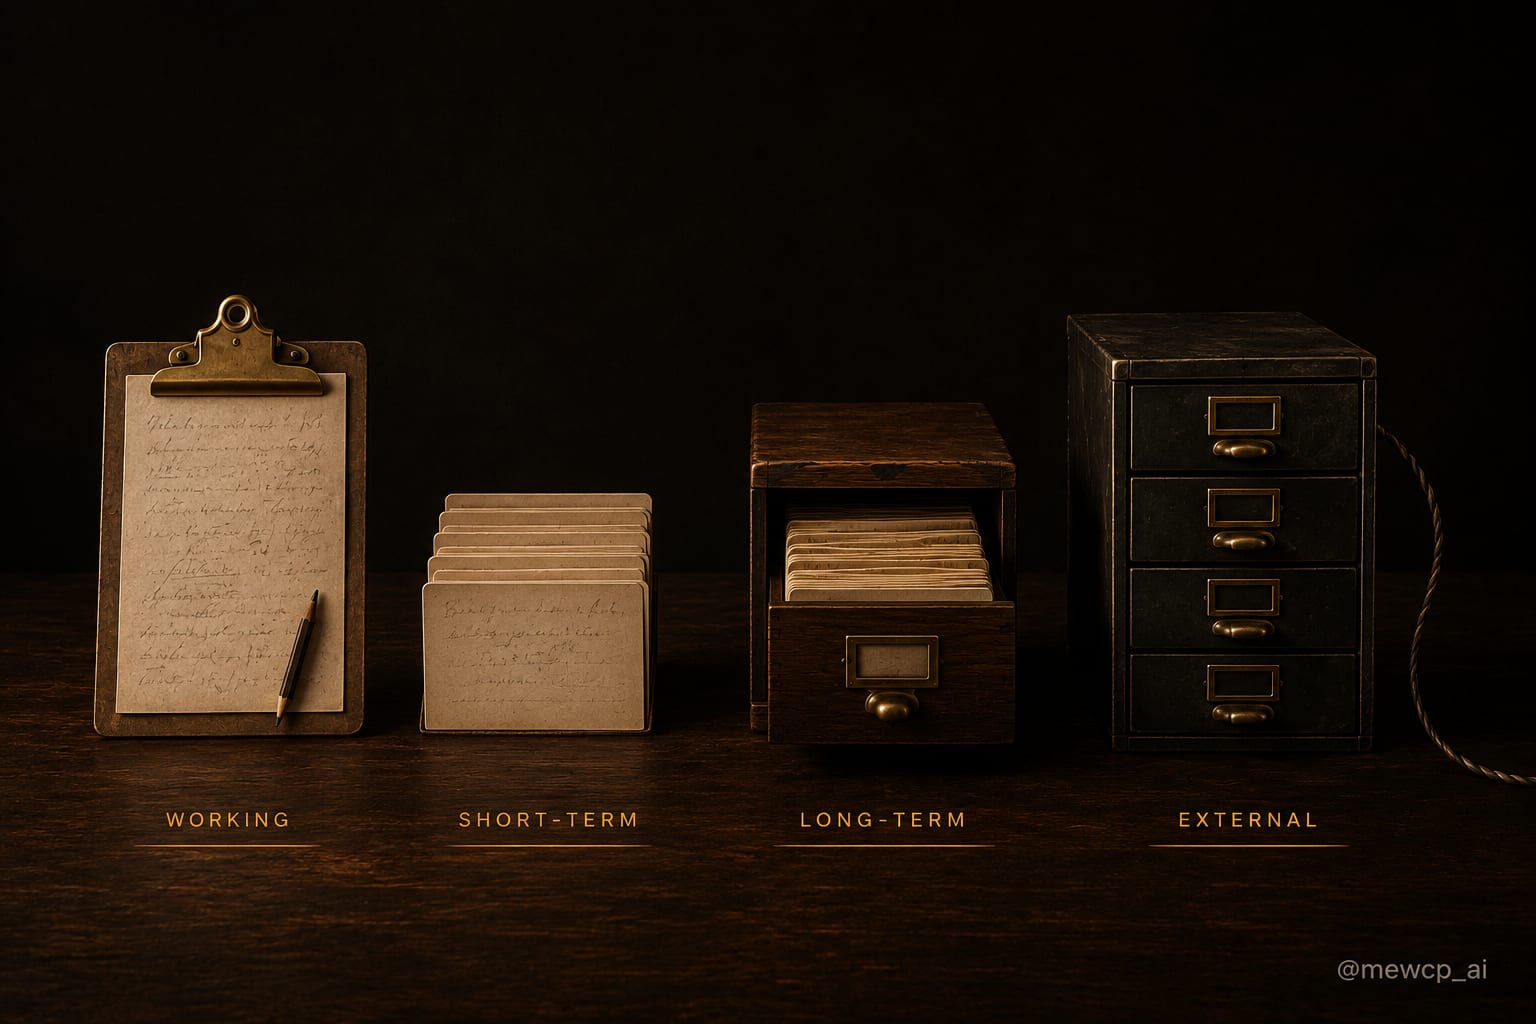
Split the one array into four stores with four different rules.
Working memory is the scratchpad for the task running right now. The current plan, the results of the last three tool calls, the retry count, the intermediate values. It is scoped to a single task run and it should be destroyed when that run finishes. If your agent restarts mid task and needs to resume, this is the only layer that has to be durable, and even then it is durable as a checkpoint, not as memory.
Short-term context is the recent conversation you resend to the model. Dialogue state, not knowledge. Its job is to keep pronouns resolvable and tone consistent. It is bounded, it gets compacted as it grows, and losing the far end of it should be survivable. If losing turn three breaks your agent, that fact should never have lived only in short-term context.
Long-term memory is the small set of facts worth keeping across sessions. Preferences, decisions, entity relationships, outcomes. This layer is written deliberately, retrieved deliberately, and it is the only layer that actually deserves the word memory. It is also the smallest. A well run agent might hold twenty long term facts per user, not two thousand.
External memory is your systems of record. Postgres, the CRM, the ticket queue, the docs. The agent reads them live through tools. It does not own them and it must not copy them, because the moment you copy a row into a memory store you have created a cache with no invalidation strategy.
Notice that only one of these four layers is a "memory system" in the way people usually mean it. The other three are context management, task state and plain data access. Calling all four "memory" is what makes the topic confusing.
One Ticket, Four Layers
A support agent handling a refund touches all four at the same time.
Working memory holds the plan for this specific ticket: verify the order, check the refund window, issue or escalate. Short-term context holds the last six turns so the agent knows what "the second one" refers to. Long-term memory holds that this customer ships to Berlin and has previously asked not to be called. External memory holds the order row, the current refund policy and the payment status, all of which the agent must read fresh because any of them could have changed since the last message.
If you collapse those into one transcript, the Berlin preference gets trimmed, the order status goes stale, and the plan competes with the dialogue for space.
Writing To Long-Term Memory
This is where most implementations go wrong. They write everything, on the theory that more memory is better memory. Three weeks later, retrieval returns forty near duplicate facts and the prompt is worse than it was with no memory at all.
A fact earns a long term slot only if it passes four tests. It has to be durable, meaning it is still likely to be true next month. It has to be specific, meaning it is actionable rather than vague sentiment. It has to be about a stable entity, a user, an account, a project, not about this conversation. And it has to be non derivable, meaning you cannot just read it from a system of record on demand.
"User prefers email over phone" passes. "User seems frustrated" fails the durability test. "User's order 4417 shipped Tuesday" fails the non derivable test, because that lives in your orders table and your table is more correct than your memory store will ever be.
Here is a small store that enforces scoping and supersession. It is deliberately boring, because memory infrastructure should be.
import json
import sqlite3
import time
from dataclasses import dataclass

SCHEMA = """
CREATE TABLE IF NOT EXISTS memories (
    id            INTEGER PRIMARY KEY AUTOINCREMENT,
    subject_id    TEXT NOT NULL,
    key           TEXT NOT NULL,
    value         TEXT NOT NULL,
    source        TEXT NOT NULL,
    confidence    REAL NOT NULL DEFAULT 0.8,
    created_at    REAL NOT NULL,
    superseded_by INTEGER
);
CREATE INDEX IF NOT EXISTS idx_active
    ON memories (subject_id, key, superseded_by);
"""


@dataclass
class Memory:
    key: str
    value: str
    confidence: float
    created_at: float


class MemoryStore:
    def __init__(self, path: str = "memory.db"):
        self.db = sqlite3.connect(path)
        self.db.executescript(SCHEMA)

    def write(self, subject_id: str, key: str, value: str,
              source: str, confidence: float = 0.8) -> int:
        """Write a fact. Any earlier fact with the same key is superseded."""
        cur = self.db.cursor()
        cur.execute(
            "INSERT INTO memories "
            "(subject_id, key, value, source, confidence, created_at) "
            "VALUES (?, ?, ?, ?, ?, ?)",
            (subject_id, key, value, source, confidence, time.time()),
        )
        new_id = cur.lastrowid
        cur.execute(
            "UPDATE memories SET superseded_by = ? "
            "WHERE subject_id = ? AND key = ? "
            "AND id != ? AND superseded_by IS NULL",
            (new_id, subject_id, key, new_id),
        )
        self.db.commit()
        return new_id

    def recall(self, subject_id: str, limit: int = 12) -> list[Memory]:
        """Return active facts, highest confidence first, newest as tiebreak."""
        rows = self.db.execute(
            "SELECT key, value, confidence, created_at FROM memories "
            "WHERE subject_id = ? AND superseded_by IS NULL "
            "ORDER BY confidence DESC, created_at DESC LIMIT ?",
            (subject_id, limit),
        ).fetchall()
        return [Memory(*row) for row in rows]

    def forget(self, subject_id: str, key: str) -> None:
        self.db.execute(
            "UPDATE memories SET superseded_by = -1 "
            "WHERE subject_id = ? AND key = ? AND superseded_by IS NULL",
            (subject_id, key),
        )
        self.db.commit()
Two details matter more than they look. Writes supersede instead of overwriting, so you keep an audit trail and can answer "why did the agent think that" six weeks later. And recall takes a hard limit, because an unbounded recall is just a slower way to blow your context budget.
The extraction step that decides what to write should be a separate, cheap model call at the end of a turn, not something the main agent does inline. Ask it for structured output and reject anything that fails the four tests.
EXTRACTION_PROMPT = """Extract durable facts about the user from this exchange.

Only include a fact if all of these are true:
- it is still likely to be true in one month
- it is specific and actionable, not a mood or a guess
- it is about the person or their account, not about this conversation
- it cannot be looked up in a database or CRM

Return JSON: {"facts": [{"key": "snake_case_key", "value": "short string",
"confidence": 0.0 to 1.0}]}
Return {"facts": []} if nothing qualifies. Do not invent facts.
"""


def persist_facts(store: MemoryStore, subject_id: str, raw_json: str) -> int:
    data = json.loads(raw_json)
    written = 0
    for fact in data.get("facts", []):
        if fact.get("confidence", 0) < 0.6:
            continue
        store.write(subject_id, fact["key"], fact["value"],
                    source="extraction", confidence=fact["confidence"])
        written += 1
    return written
Assembling One Turn
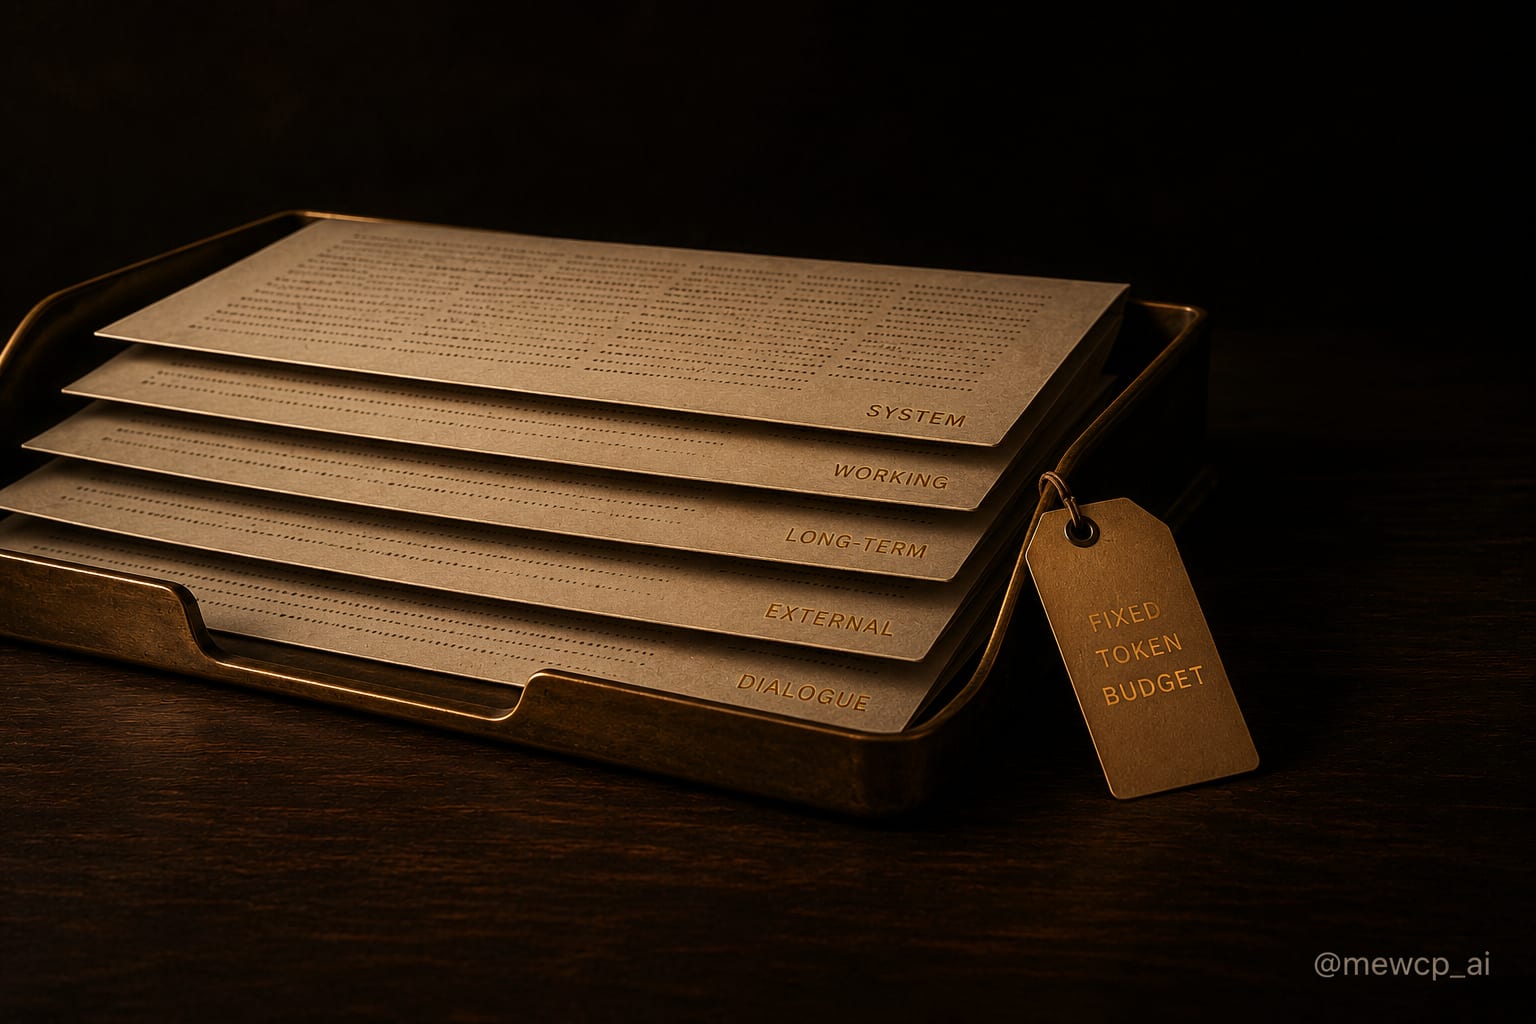
Retrieval is a budget problem, not a search problem. You have a fixed number of tokens and four layers competing for them. Decide the order once, in code, rather than letting whatever ran last win.
The order I use, highest priority first: system instructions, then working memory for the current task, then long term facts, then external data fetched for this specific step, then short-term dialogue, trimmed to whatever space is left.
Long term facts go near the top because they are small and they change behaviour. Dialogue goes last because it is large and it degrades gracefully.
def build_context(store, subject_id, task_state, tool_results,
                  history, budget_tokens=8000, est=lambda s: len(s) // 4):
    blocks = []
    used = 0

    def add(text):
        nonlocal used
        cost = est(text)
        if used + cost > budget_tokens:
            return False
        blocks.append(text)
        used += cost
        return True

    add(f"CURRENT TASK\n{task_state}")

    facts = store.recall(subject_id, limit=12)
    if facts:
        rendered = "\n".join(f"- {m.key}: {m.value}" for m in facts)
        add(f"KNOWN ABOUT THIS USER\n{rendered}")

    for result in tool_results:
        if not add(f"TOOL RESULT\n{result}"):
            break

    for turn in reversed(history):
        if not add(turn):
            break

    return "\n\n".join(blocks)
Cap the long term block. Twelve facts is a reasonable default and it forces the confidence ranking to do real work. If you find yourself needing fifty, your write policy is too loose.
Forgetting Is The Hard Part
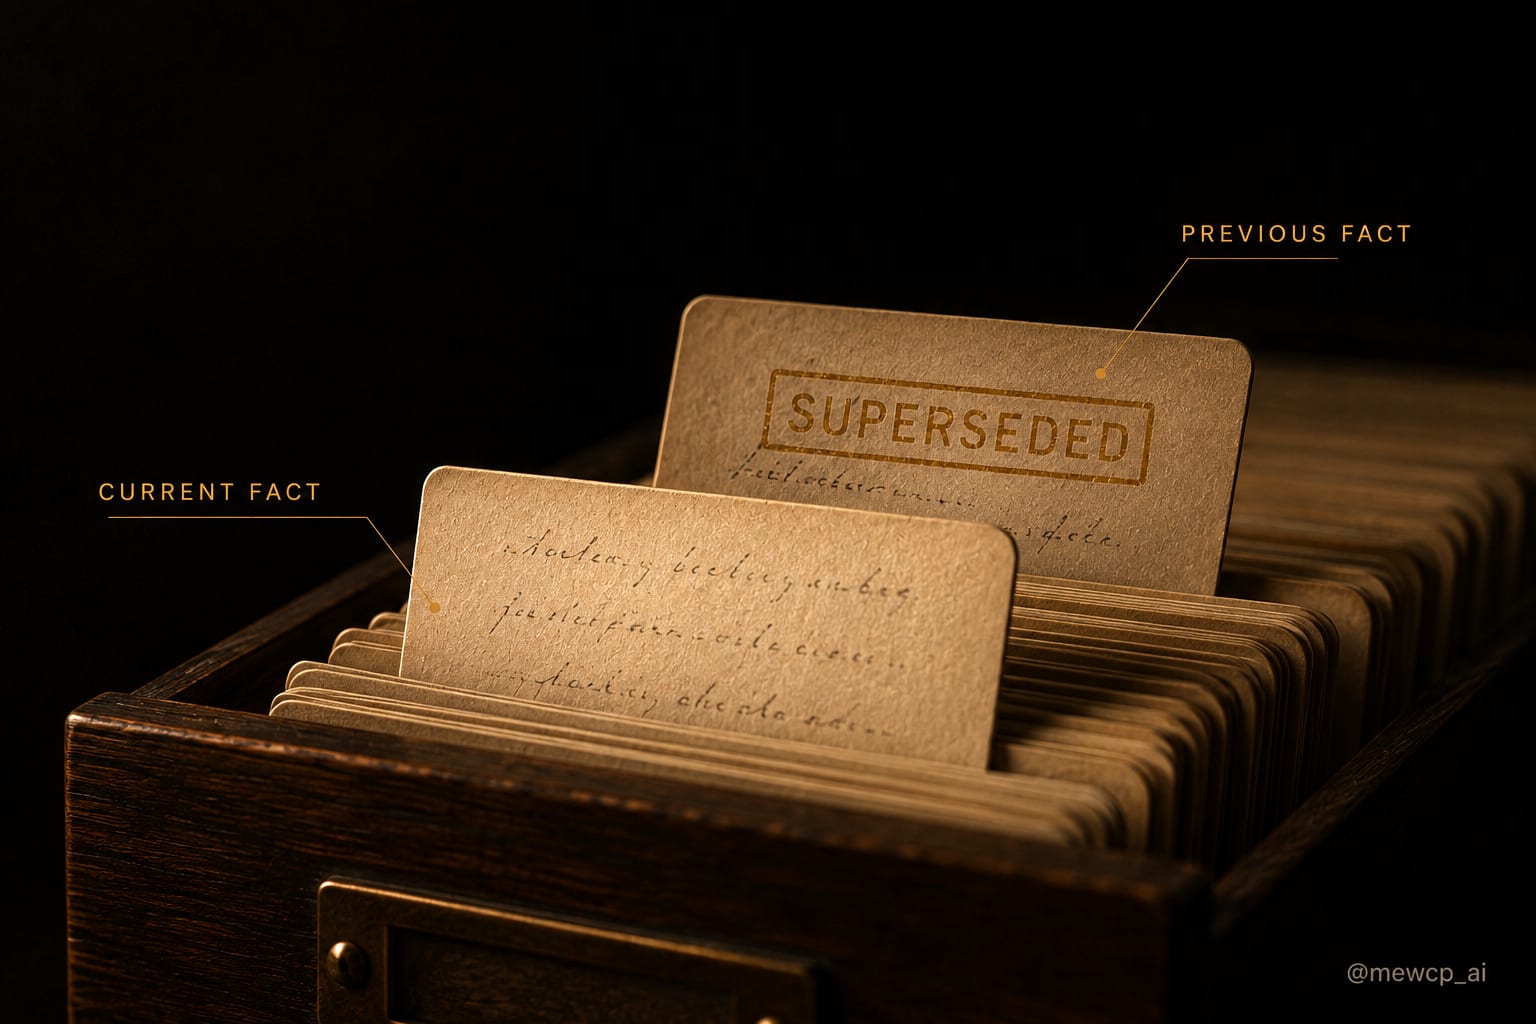
Writing memory is easy. Keeping it true is the job.
Contradiction. A user says they prefer email, then three months later asks to be called. Both statements were true when made. Your store needs a key based supersession rule so the new fact wins automatically, which is exactly what the write method above does. Without it you will retrieve both and the model will pick one at random.
Decay. Not every fact ages the same way. A dietary restriction is stable. A "currently working on the Q3 migration" fact is worthless in six months. Attach a decay half life per fact type and let confidence fall over time, then filter on confidence at recall.
Poisoning. If your extraction step reads tool output or user supplied documents, someone can write instructions into your long term memory. Treat extracted facts as untrusted data. Never let a memory string be interpolated into a position where the model would read it as an instruction, and keep the memory block clearly framed as data.
Growth. Memory stores grow monotonically unless something prunes them. Run a periodic job that drops superseded rows past a retention window and merges near duplicate keys. Do this before it becomes a problem, because at 500 facts per user your recall quality is already gone.
Where External Memory Fits
Notice that nothing above touches your database. That is on purpose.
External memory should be read through tools at the moment it is needed, never copied into a memory store. The order status, the current pricing, the open tickets, the document contents. Fetch them fresh, use them in the turn, let them go. What you can store is a pointer, for example active_order_id: 4417, which is small, durable and always resolved against the real system.
This is where a tool layer stops being optional. Every external memory read is an authenticated call into a real system, usually on behalf of a specific user, and the hard parts are credential isolation and multi-tenancy rather than the fetch itself. If you are building that layer yourself, budget for auth, token refresh, per tenant scoping and audit logging. Hosted MCP servers and an MCP gateway exist to take that piece off your plate, which is the part of the problem MewCP works on. Either way, the design rule is the same: external memory is fetched, not stored.
Before You Ship
- Every fact you store has an explicit lifespan: step, session, user, or system of record
- Working memory is destroyed when the task completes
- Short-term context has a hard cap and a compaction strategy
- Long-term writes go through a policy check, not a blanket append
- Writes supersede by key so contradictions resolve automatically
- Recall has a hard limit and a confidence threshold
- Nothing that lives in a database is duplicated into long-term memory
- Extracted memories are treated as untrusted data, never as instructions
- A pruning job exists and has actually run at least once
- You can answer "why did the agent think that" from the audit trail
Get these ten right and your agent will feel like it remembers you. Get them wrong and no context window will save it.